Observability
The missing chicken - why you need to check handoffs between AI agents
In minute 25 of an LLM-powered Minecraft survival run, an agent called Ada had two cooked chickens …
Is the cheap model good enough? How to test a new model in your agent
Last week a paper called GVS5H (Gorilla vs 5 humans) hit the top of Hacker News with an interesting …
I put a ghost in Claude Code. Then I evaluated it
TLDR; I built a Halloween Claude Code mod that grades each turn as a treat or a trick and blocks …
EU AI Act compliance for AI agents: building the engineering foundation with Arize and evroc
The EU AI Act’s high-risk obligations read like an engineering spec: automatic logs, …
Claude's hillclimb loop, with your traces underneath
On September 28, Anthropic’s Lance Martin published Automating eval design and hillclimbing …
NVIDIA proposes an AI agent kill switch in silicon after a year of sandbox escapes
TL;DR: NVIDIA’s new Open Agent Safety Platform assumes an agent can’t police itself, so …
SLMs for custom tasks: when small models beat frontier ones, and how to be sure
On the first of September, Tobi Lütke, the CEO of Shopify, posted something on X that interested me: …
A Skill Is Just an Agent. So Measure Your Changes.
TL;DR: A skill is just an agent, a prompt running in a harness, so you can test a change to it …
The EU AI Act wants a record. Your traces are already most of one.
I read a piece by Angie Jones from the Agentic AI Foundation this week, The EU AI Act and the new …
Evals Are a Revenue Strategy, Not a Safety Net
Here’s the moment every AI team knows. You have a demo that works. Not always, but most runs, …
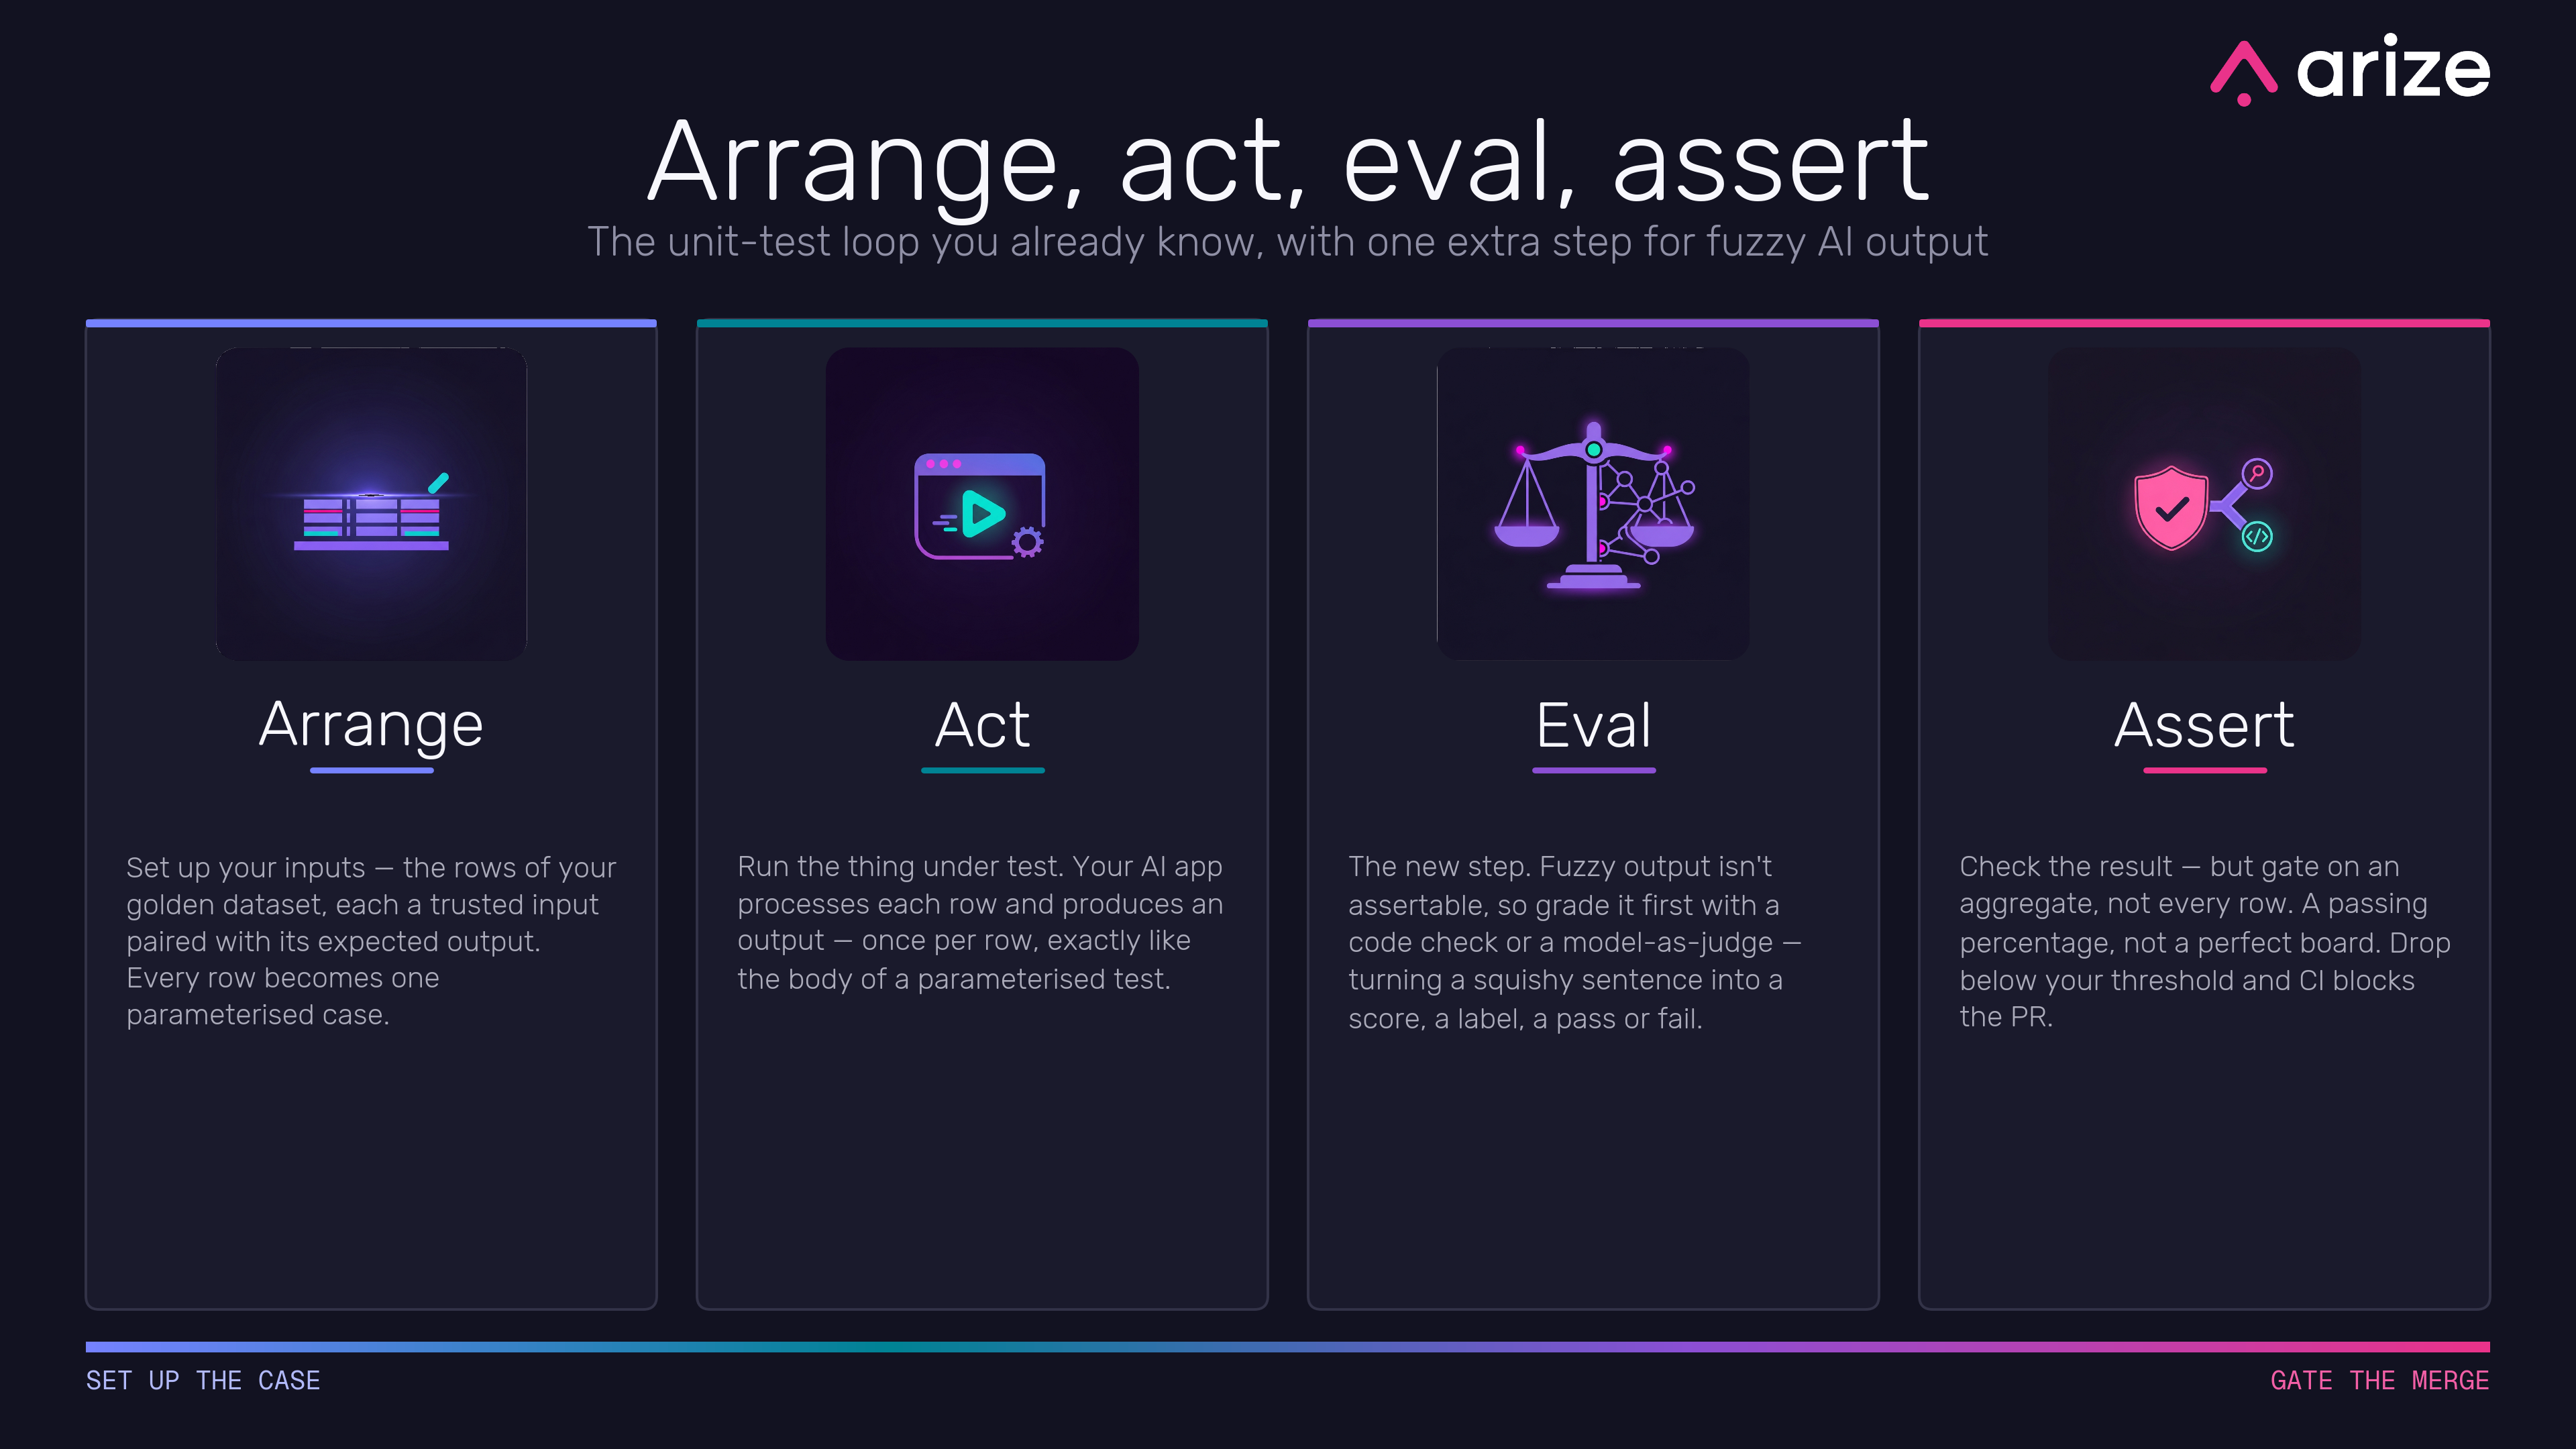
Evals belong in your CI/CD pipeline
The other day I wrote that evals are just testing - the same old loop of “decide what good …
AI evals are just testing (with a much weirder answer key)
Years ago, before “AI” meant chatbots and before anyone said the word “eval” …