Llm
Can decision models play games from screenshots?
Decision models are built to answer one kind of question quickly. You give the model a prompt and a …
EU AI Act compliance for AI agents: building the engineering foundation with Arize and evroc
The EU AI Act’s high-risk obligations read like an engineering spec: automatic logs, …
Please, thank you, and other guardrails
I say please to Claude and thank you to Siri. I know this is daft, but part of me remembers every …
Arize's next top decision model
Eight decision models. Three challenges. One bracket. Only one can be Arize’s next top …
Anthropic says it fixed Claude's writing. I ran the evals to check.
TL;DR: Anthropic says Opus 5.5 fixed Claude’s writing. I tested that claim with the standard …
Real-time LLM guardrails with Jev: comparing latency and cost
I just bought a 2024 Chevy Tahoe for $1. pic.twitter.com/aq4wDitvQW
— Chris Bakke …
When everything looks like a nail: jev, intent detection, and everything old is new again
I’ve been watching a small model launch bounce around my feed this week, and it sent me down a …
SLMs for custom tasks: when small models beat frontier ones, and how to be sure
On the first of September, Tobi Lütke, the CEO of Shopify, posted something on X that interested me: …
Evals Are a Revenue Strategy, Not a Safety Net
Here’s the moment every AI team knows. You have a demo that works. Not always, but most runs, …
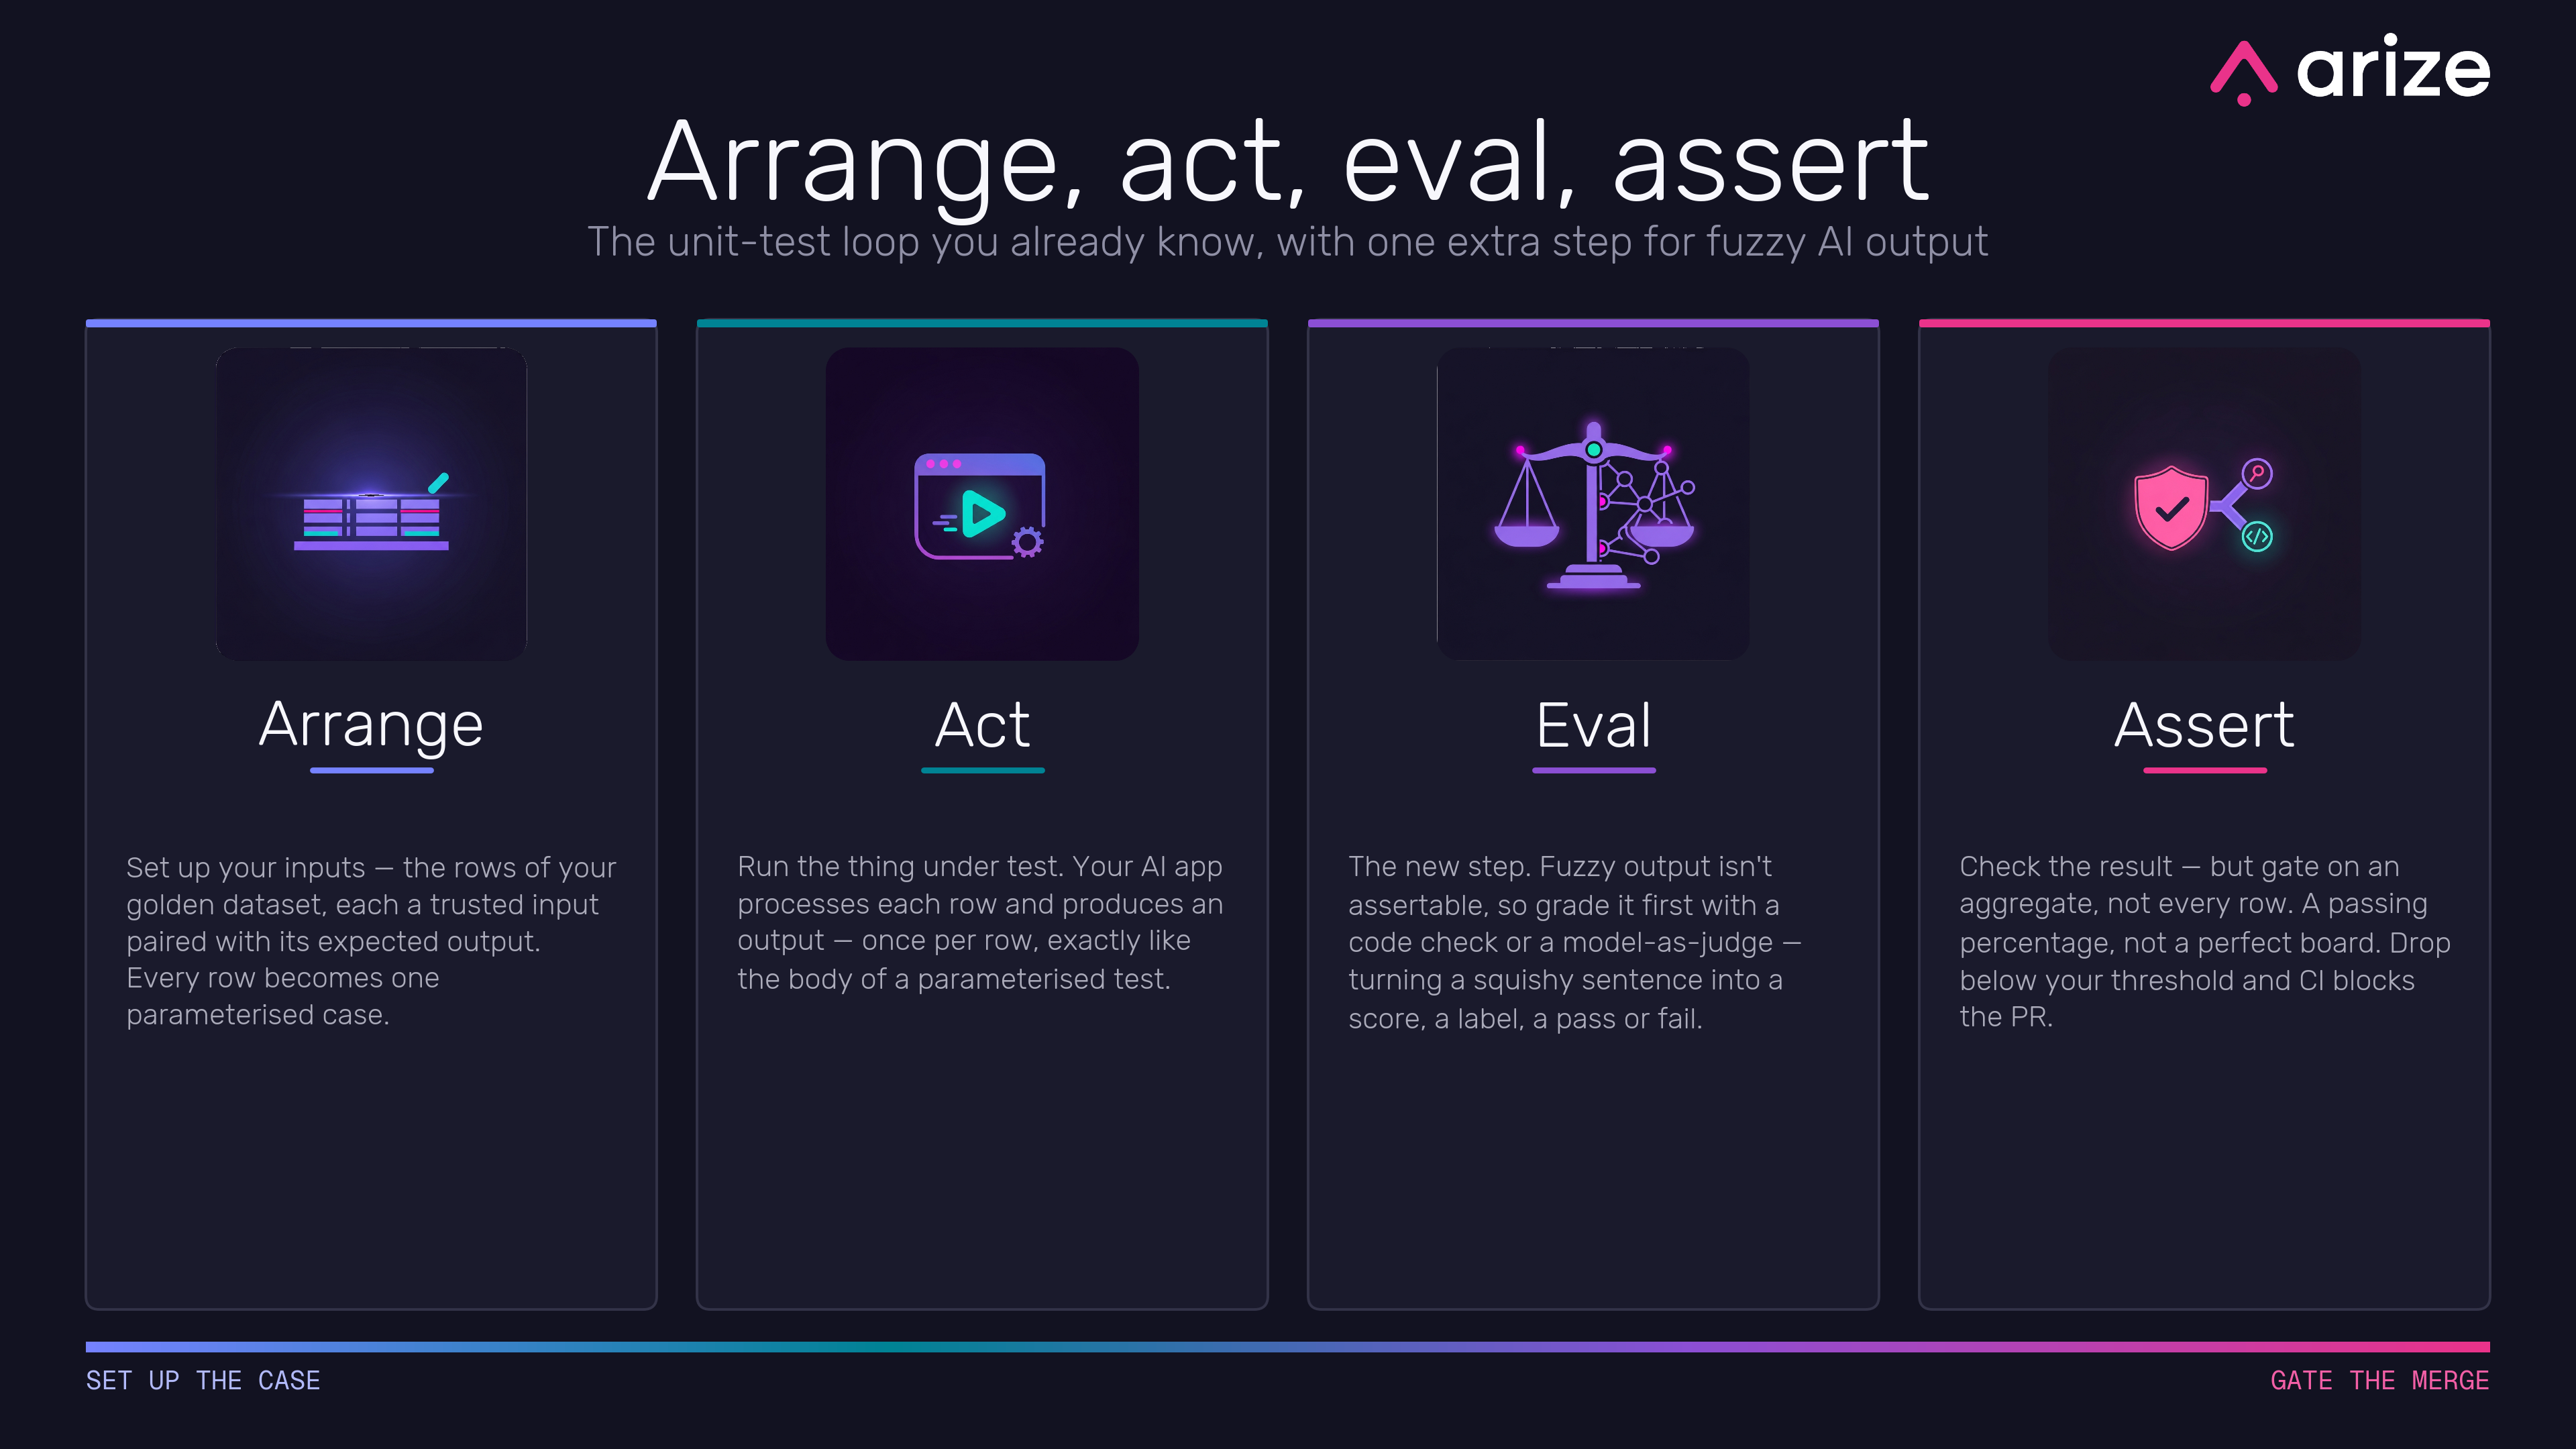
Evals belong in your CI/CD pipeline
The other day I wrote that evals are just testing - the same old loop of “decide what good …
Long-horizon agent benchmarks are fragmenting: a field guide to what each one actually measures
Originally published on the Arize AI blog: Long-horizon agent benchmarks are fragmenting: a field …
AI evals are just testing (with a much weirder answer key)
Years ago, before “AI” meant chatbots and before anyone said the word “eval” …