Evals
Real-time LLM guardrails with Jev: comparing latency and cost
I just bought a 2024 Chevy Tahoe for $1. pic.twitter.com/aq4wDitvQW
— Chris Bakke …
When everything looks like a nail: Jev, intent detection, and everything old is new again
I’ve been watching a small model launch bounce around my feed this week, and it sent me down a …
SLMs for custom tasks: when small models beat frontier ones, and how to be sure
On the first of September, Tobi Lütke, the CEO of Shopify, posted something on X that interested me: …
A Skill Is Just an Agent. So Measure Your Changes.
TL;DR: A skill is just an agent, a prompt running in a harness, so you can test a change to it …
The two-person team: the domain expert prompts, the engineer connects
At RenderATL I had the same conversation twice, from two different sides.
The first was at the …
Your eval criteria are already written, just scattered across three systems
In an earlier post I built a self-improving agent by mining a context graph out of data the team …
Evals Are a Revenue Strategy, Not a Safety Net
Here’s the moment every AI team knows. You have a demo that works. Not always, but most runs, …
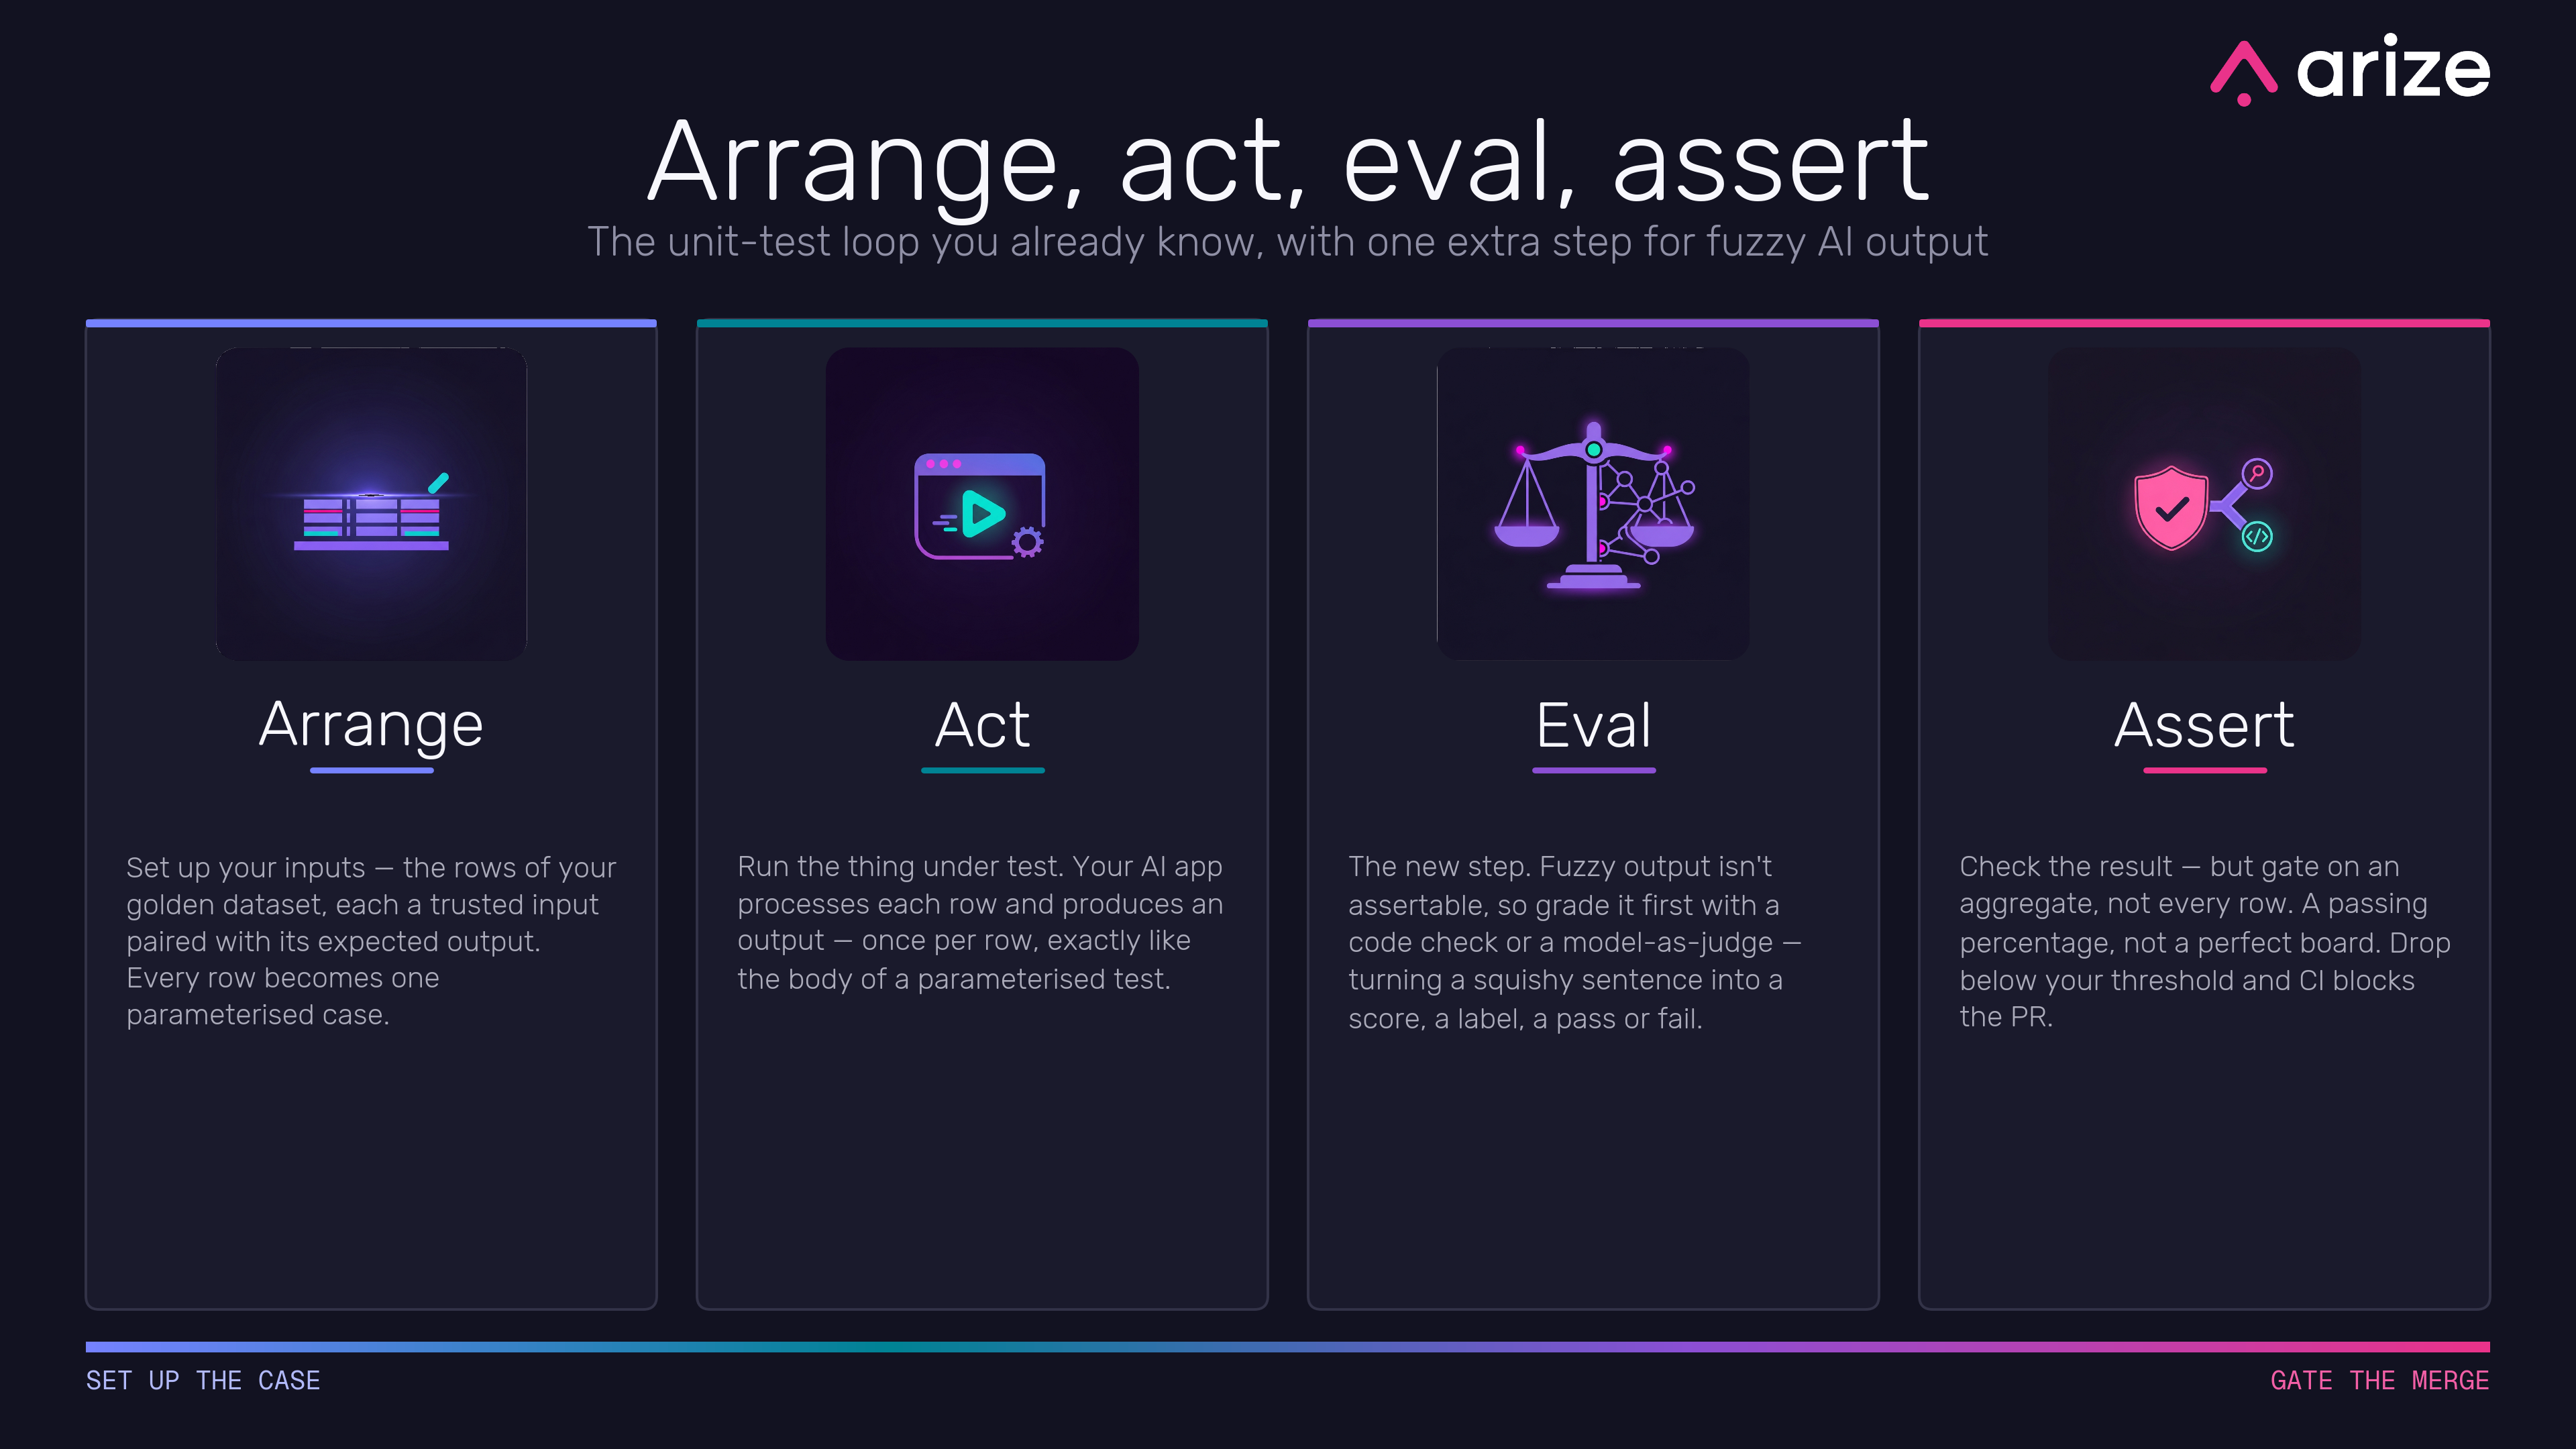
Evals belong in your CI/CD pipeline
The other day I wrote that evals are just testing - the same old loop of “decide what good …
Long-horizon agent benchmarks are fragmenting: a field guide to what each one actually measures
Originally published on the Arize AI blog: Long-horizon agent benchmarks are fragmenting: a field …
AI evals are just testing (with a much weirder answer key)
Years ago, before “AI” meant chatbots and before anyone said the word “eval” …
The Phoenix Project still holds up, even if you replaced all the code with agents
I reread The Phoenix Project last month. I do this every year or two — it’s one of those books …
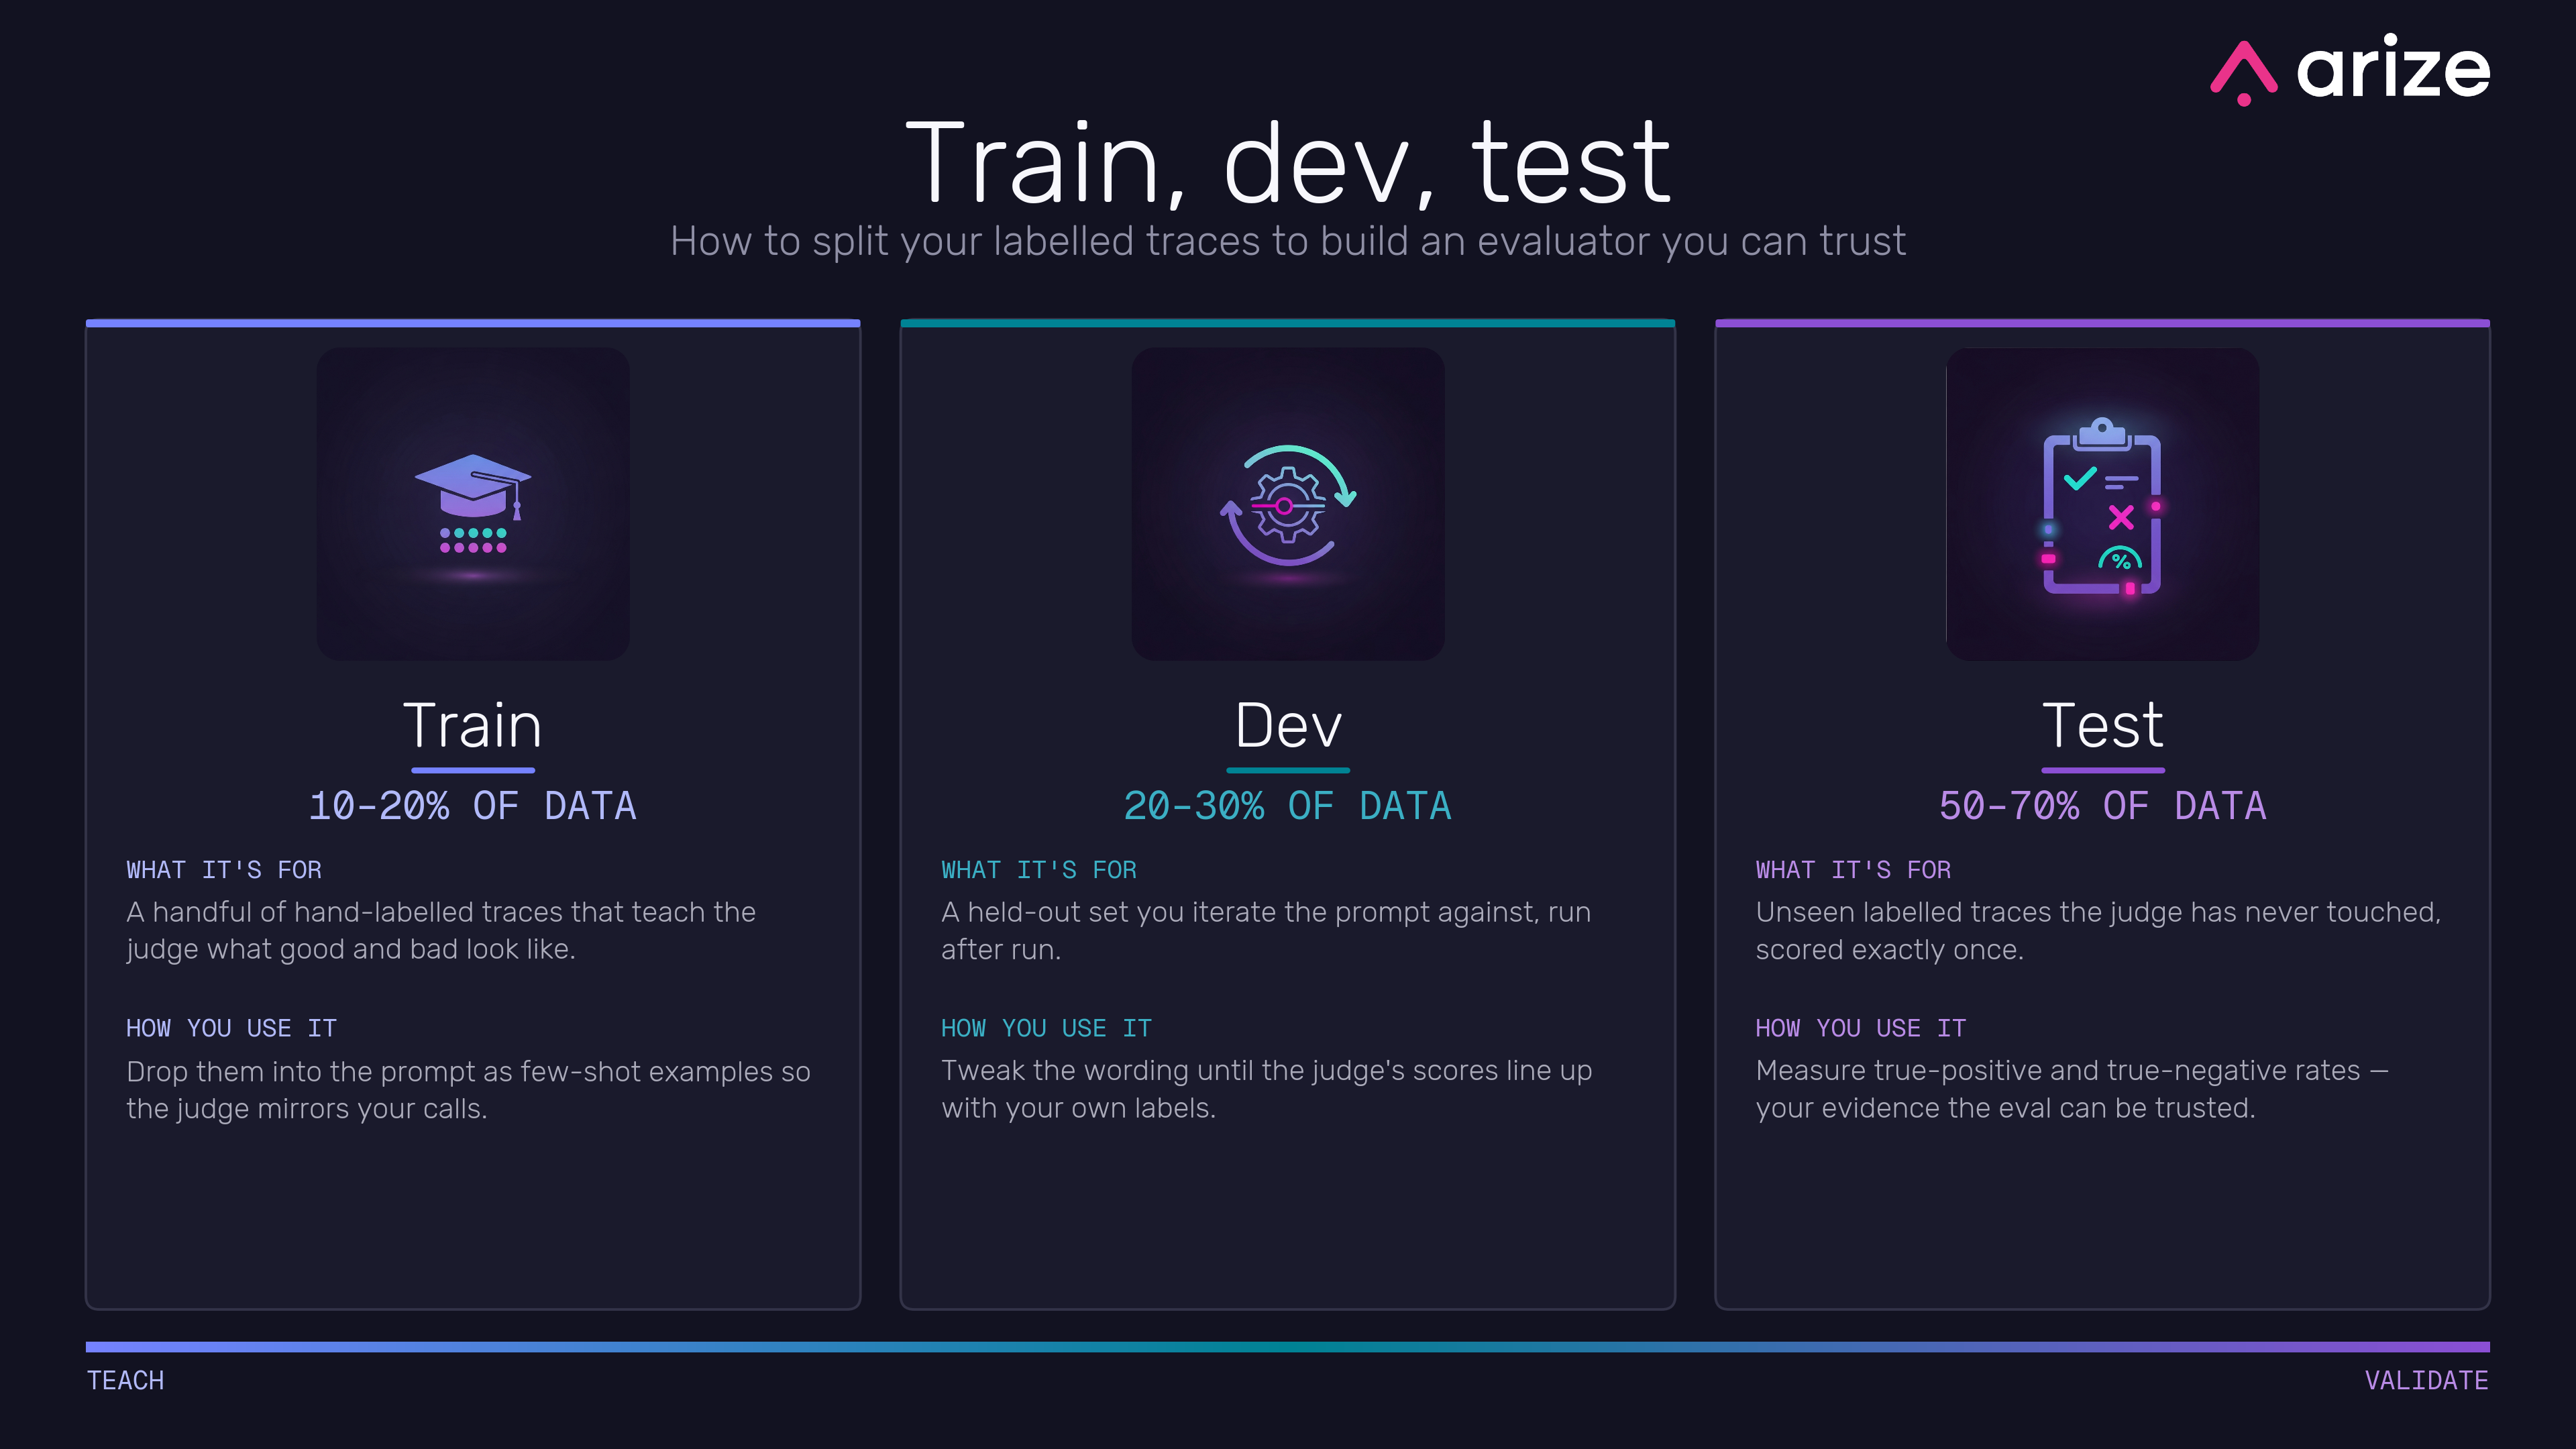
Train, dev, test: the split that makes an LLM judge trustworthy
Say you’ve built an LLM judge and you want to know if it’s any good. The obvious move is …