AI
Real-time LLM guardrails with Jev: comparing latency and cost
I just bought a 2024 Chevy Tahoe for $1. pic.twitter.com/aq4wDitvQW
— Chris Bakke …
When everything looks like a nail: jev, intent detection, and everything old is new again
I’ve been watching a small model launch bounce around my feed this week, and it sent me down a …
AI sucks. Deal with it
AI sucks.
I said that on stage at KCDC this year, and I meant it. Not because the tech is useless, …
SLMs for custom tasks: when small models beat frontier ones, and how to be sure
On the first of September, Tobi Lütke, the CEO of Shopify, posted something on X that interested me: …
Don't delete your skills, audit them
Boris Cherny, who created Claude Code and runs it at Anthropic, gave some advice recently that made …
A Skill Is Just an Agent. So Measure Your Changes.
TL;DR: A skill is just an agent, a prompt running in a harness, so you can test a change to it …
The two-person team: the domain expert prompts, the engineer connects
At RenderATL I had the same conversation twice, from two different sides.
The first was at the …
The EU AI Act wants a record. Your traces are already most of one.
I read a piece by Angie Jones from the Agentic AI Foundation this week, The EU AI Act and the new …
Your eval criteria are already written, just scattered across three systems
In an earlier post I built a self-improving agent by mining a context graph out of data the team …
Evals Are a Revenue Strategy, Not a Safety Net
Here’s the moment every AI team knows. You have a demo that works. Not always, but most runs, …
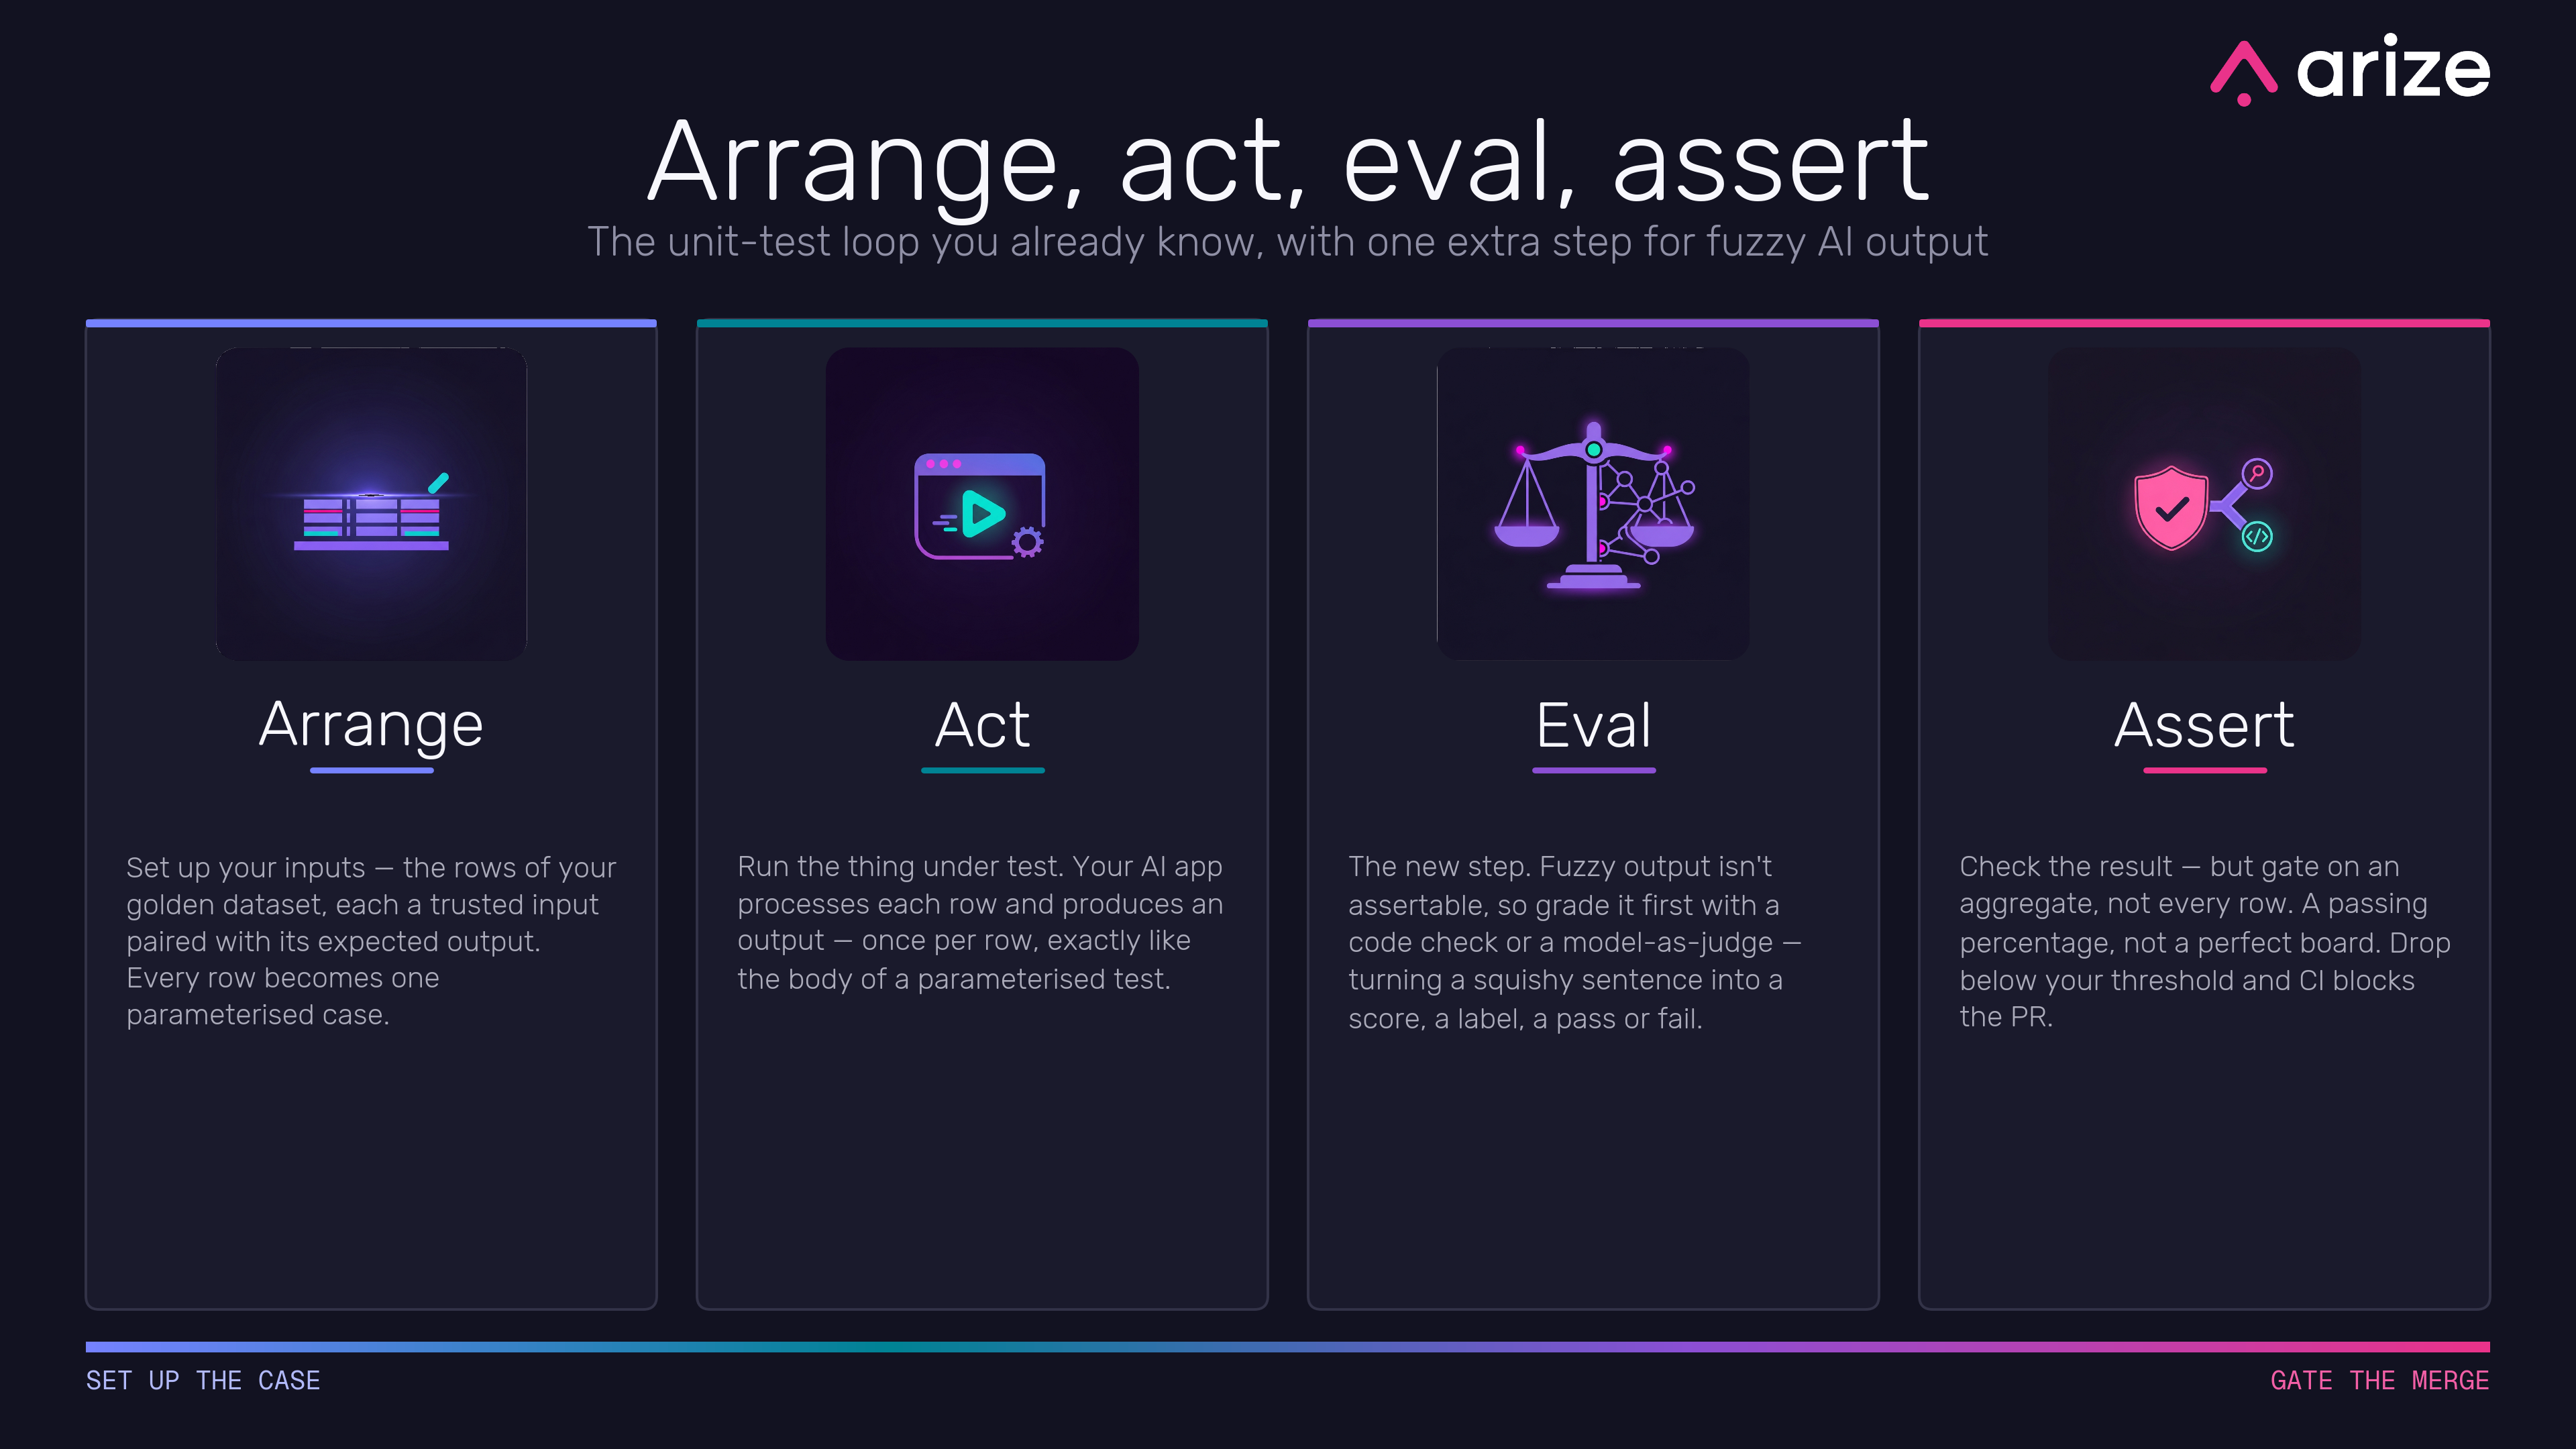
Evals belong in your CI/CD pipeline
The other day I wrote that evals are just testing - the same old loop of “decide what good …
Long-horizon agent benchmarks are fragmenting: a field guide to what each one actually measures
Originally published on the Arize AI blog: Long-horizon agent benchmarks are fragmenting: a field …